CFM: Language-aligned Concept Foundation Model for Vision
European Conference on Computer Vision (ECCV) 2026 (Spotlight)
TL;DR
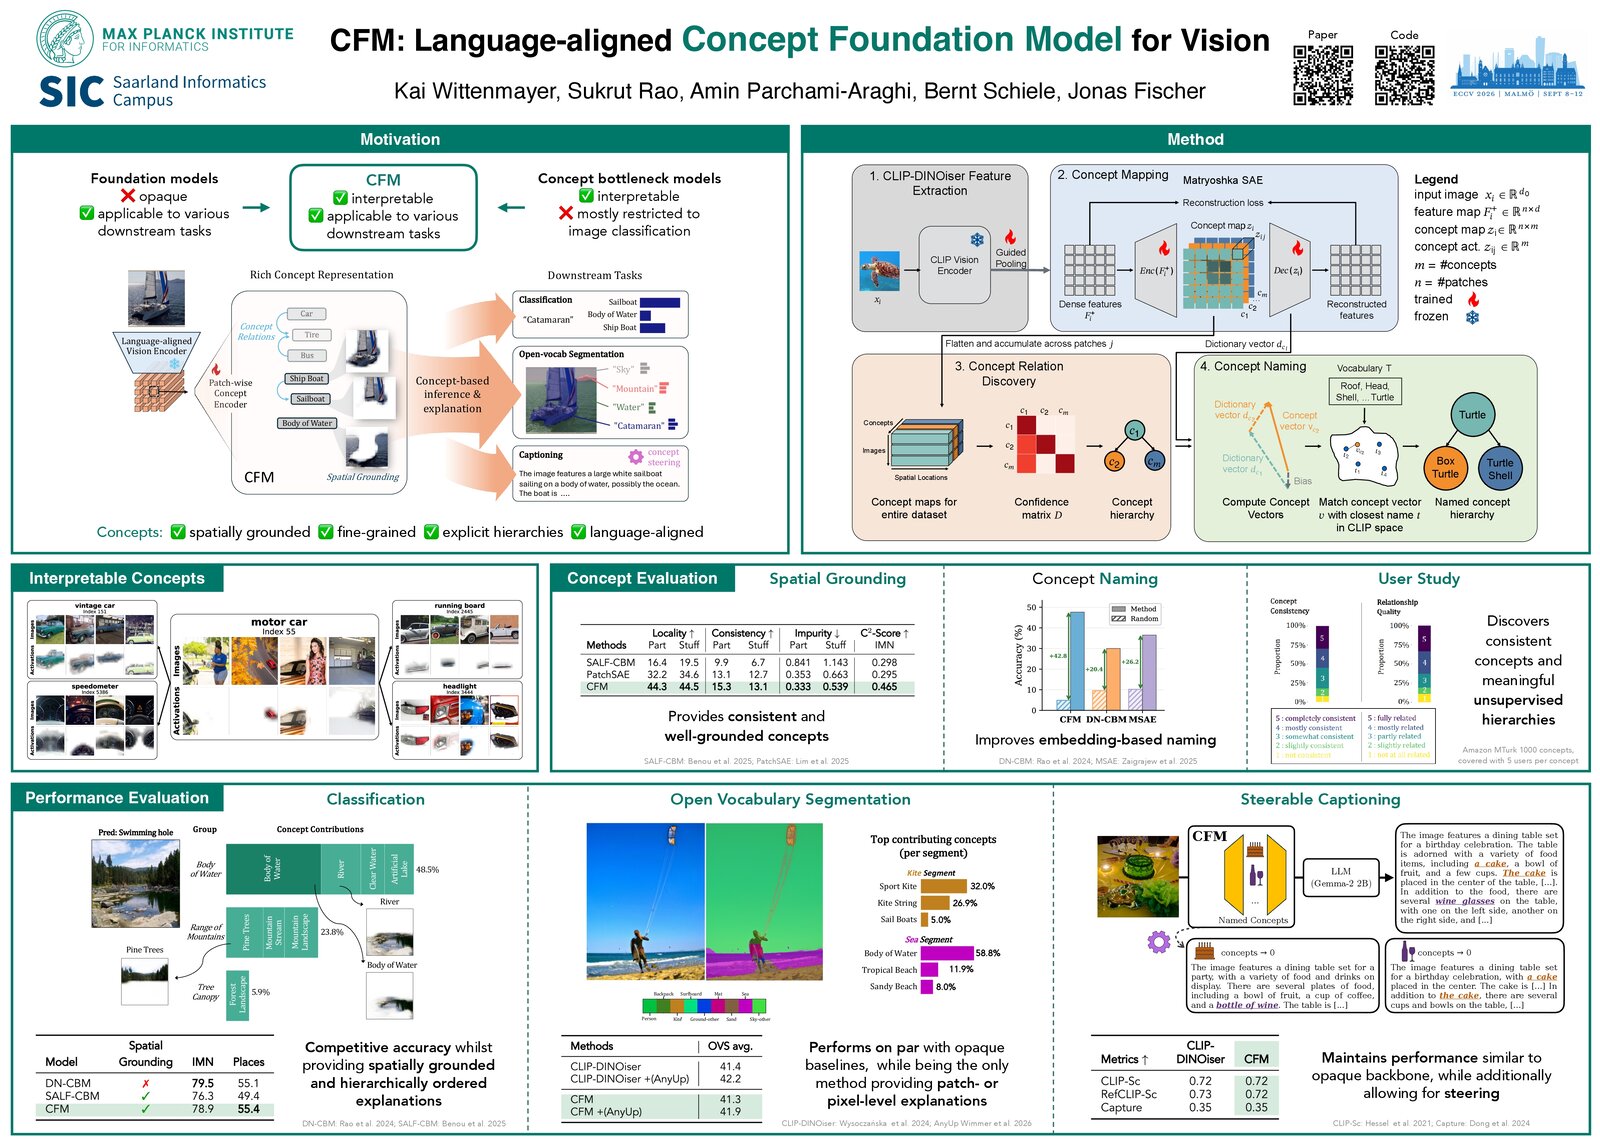
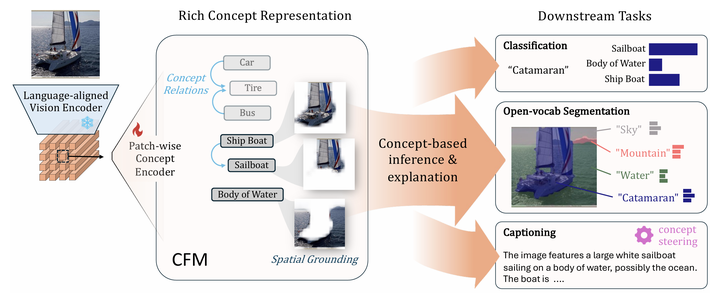
CFM is a language-aligned concept foundation model that extracts spatially localized, visually grounded, and human-interpretable concepts at various granularities from images, organizes them into hierarchies, automatically assigns names to them, enabling concept-based explanations for any downstream task that the foundation model can perform, such as classification, open vocabulary segmentation, and captioning.
Video
Hosted by YouTube. Pressing play loads the video from Google, subject to their privacy policy.
Abstract
Language-aligned vision foundation models perform strongly across diverse downstream tasks. Yet, their learned representations remain opaque, making interpreting their decision-making difficult. Recent work decompose these representations into human-interpretable concepts, but provide poor spatial grounding and are limited to image classification tasks. In this work, we propose CFM, a language-aligned concept foundation model for vision that provides fine-grained concepts, which are human-interpretable and spatially grounded in the input image. When paired with a foundation model with strong semantic representations, we get explanations for any of its downstream tasks. Examining local co-occurrence dependencies of concepts allows us to define concept relationships through which we improve concept naming and obtain richer explanations. On benchmark data, we show that CFM provides performance on classification, segmentation, and captioning that is competitive with opaque foundation models while providing fine-grained, high quality concept-based explanations. Code at https://github.com/kawi19/CFM.
Poster